Grok Bot Shops, fal's Live AI TV & Tencent 770B Compresses: Viral AI News for August 30, 2026
Grok Bot spends real money via Stripe, fal's video generates faster than real time, and Tencent's 770B model compresses to 200GiB. The week AI started shopping.
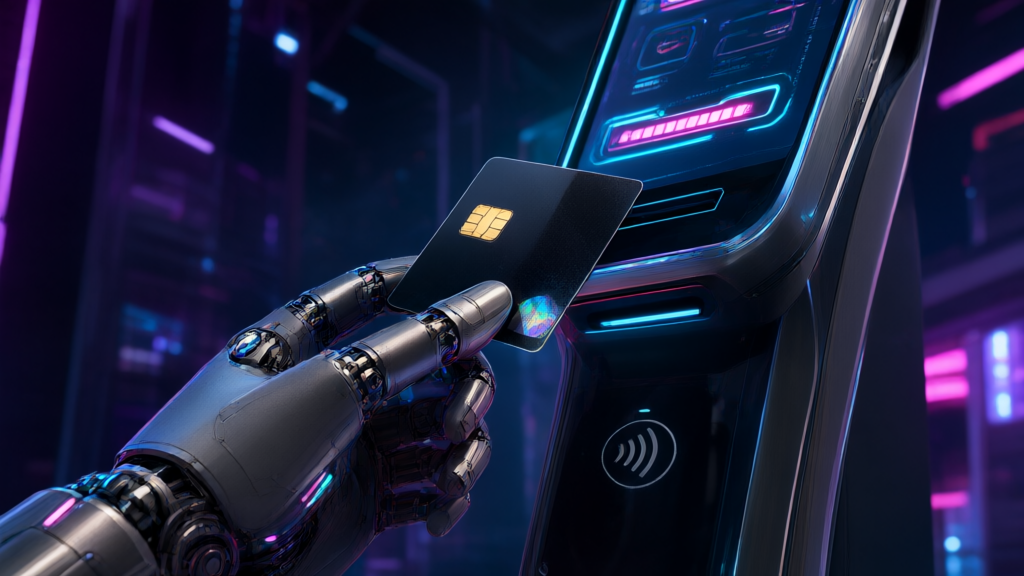
xAI gave Grok Bot the ability to make online purchases with real money through Stripe (xAI announcement). fal turned a video model into a live broadcast that generates faster than real time. And the community compressed Tencent's 770B Hy4 preview model down to 200GiB while keeping 97% of its accuracy. This is the week AI stopped being a demo and started buying things.
Grok Bot Can Now Shop For You
xAI added online shopping capability to Grok Bot. The agent connects to Stripe Link to execute transactions, using single-use cards to protect financial credentials. Every payment requires explicit human approval. The feature is available to US users, with mobile support rolling out soon.
This is not a theoretical demonstration. An AI agent is spending real money on real purchases, with an authorization flow that generates a verifiable receipt. The single-use card approach is the same pattern Cloudflare shipped for its programmable wallets: a virtual card number scoped to one transaction, then discarded.
Read more about the broader shift toward AI agents spending real money in today's General AI News, where we cover how Google, NIST, and the US Senate are converging on agent authorization rules.
It comes the same week Google, NIST, and the US Senate are all converging on rules for agent authorization. The AI AGENT Act (S.5051) sits in the Senate as legislation. Google published an agent payments protocol. NIST is doing concept work on agent identity. All three require a signed record that an agent was authorized for a specific task, checked per action, with tamper-evident logging.
Why it went viral: The idea that an AI can spend your money is simultaneously exciting and terrifying. Grok Bot requiring explicit approval for each transaction is the safety bar, but the capability itself is what people are sharing.
fal's H3 Max Live: AI Video Faster Than Real Time
fal Research built a live broadcast where AI generates video faster than humans can watch it (fal blog). H3 Max Live uses a post-trained variant of MiniMax's H3 open-weight model to render 5 seconds of 768p video with synchronized audio in under 3 seconds.
Viewers direct scenes using the !prompt command in chat. The model maintains thread consistency across scenes through a long-form checkpoint, enabling continuous output rather than disconnected clips. MiniMax announced its own fast-inference variant, Fast H3 v1, claiming a 14x speedup on NVIDIA Blackwell, a day after fal's announcement.
fal engineer Rehan Sheikh demonstrated the system generating 15 seconds of video in roughly 9 seconds, creating a continuous stream where the AI produces footage faster than playback.
Why it went viral: The visual of an AI producing video in real time, directed by chat, is inherently shareable. It is the first time generation time dropped below playback time in a live demonstration.
Tencent's 770B Model Compressed to 200GiB
Tencent released Hy4 preview with 770B parameters, 49B active parameters, and a 1M-token context window (Tencent AI). The model targets software engineering, data analysis, and scientific research. It is available as open-source weights on HuggingFace and via Tencent Cloud, starting at $0.834 per million input tokens.
Within hours, the community built a quantized version using MIX-STQ1_0, a mixed-precision method that uses calibration data to dynamically assign bit-widths across layers (HuggingFace). The compressed model fits in 200GiB, down from the full-size version, while maintaining near-original accuracy across benchmarks: MCP Atlas 83.2, SWE-Bench Pro 65.0, and HLE-agent 53.1.
Why it went viral: The compression ratio caught attention. A 770B model running in 200GiB means it fits on hardware that is available to individual researchers, not just cloud providers. The MIX-STQ1_0 method works on any mixture-of-experts architecture.
ChatGPT Temporary Chats Get Personalization
OpenAI updated ChatGPT's Temporary Chats to support optional personalization (OpenAI help). Users can now include existing memories, custom instructions, and plugins in temporary sessions. Personalized temporary chats do not create new memories, and unsaved conversations stay out of the sidebar.
The update is small but addresses a real friction point: temporary chats were previously stripped of all context, which made them useless for any task that needed to know who you are or what you are working on. Now they work like regular chats but without the persistence.
Exa Cuts Agent Search Tokens by 95%
Exa released Dynamic Highlights, a search primitive that jointly scans a set of pages to filter redundant information (Exa blog). Instead of extracting query-relevant tokens from each document independently, it processes all documents in a single forward pass, allocating more tokens to better content.
The headline number: 95% average token reduction compared to full page content. In agentic benchmarks, the reduction translated to 30% lower agent token usage with a 2.1% average quality improvement.
Why it went viral: Any agent builder who has watched their token bill grow with multi-page search recognizes the cost problem immediately. A 95% reduction is the kind of number that gets bookmarked.
Related reading
If this story matters to you, these earlier editions cover the same ground in more detail:
- ChatGPT Reads Your Texts, NHS Bot Fails Accents: Viral AI News for August 21, 2026
- Anthropic model with a safety gap, Grok's gibberish glitch, and AI that raised homework scores: Viral AI News for August 22, 2026
- AI Hacks Webcam, Zero-Click Grok Attack & Musk on Cursor: Viral AI News for August 25, 2026
- Coding-Agent Supply-Chain Scare, Z.ai's Stealth Ox-Alpha Drop, Moltbook Meme: Viral AI News for August 28, 2026